

☆ Yσɠƚԋσʂ ☆
- 410 Posts
- 396 Comments

People who built their whole identity around hating LLMs really do need to get a new hobby.

This is just such an idiotic line argument. It’s as if StackOverflow didn’t exist before LLMs and there weren’t whole memes about copy/paste driven development. You’re literally making the same argument as RIAA here, it’s pathetic.



 6·2 days ago
I found this app was really helpful getting started https://www.superchinese.com/
It breaks things up into short lessons, and it has voice recognition so you can practice speaking and see whether you’re pronouncing things correctly. After you get comfortable listening and reciting the phrases a bit, I also recommend watching youtube channels like Lazy Chinese. They break things up by comprehension level, so you can start with beginner, and work your way up. Eventually, it really helps to practice with a native speaker. If you have any classes offered in town or know anybody who speaks Mandarin that’d be willing to help you practice, that’s ultimately how you get to the point where you can really talk to people.
My advice is not to worry about writing characters to start, and don’t worry too much about tones. They are important, but people will understand you from context most of the time if you get some wrong. It’s also easier to learn tones in the context of a sentence. I still have trouble with tones if I just pronounce an individual word, but when I speak a sentence, I’ve learned to recognize the cadence, so I get them right most of the time now.
 8·3 days ago
Just vassal states doing vassal things.
Never too late, I started a couple of years ago and now I’m conversational.


quite possibly
 21·3 days ago
There’s nothing magic about LLMs, but I think we’ve said everything there is to say here, and we’re just going in circles now.
Hence, why discussion of whether LLMs were used or not is actively harmful. If you focus on the code and its quality then the whole problem goes away entirely. The person is responsible for the code and what tool they used is irrelevant. Your approach creates a whole new problem that didn’t exist in the first place.
Anybody who’s actually worked with these tools knows that you absolutely can’t just provide wishes for features and end up with anything remotely resembling quality code. And telling whether a human was involved in writing the code or not isn’t hard at all because LLM written code always looks like shit.
The harm in focusing on the tool rather than the code is pretty obvious. Doing so dilutes the responsibility of the developer, since now they can say the LLM introduced a bug or made a bad decision. When the ownership rests with the human, then they are responsible for the code and what it does. How the code was produced is also completely irrelevant, Either the code is clean and it does what it says or not. Nothing else actually matters.
It’s a different workflow, but all LLM does is just more automation. The intention and the ideas still come from the developer, just because the tool automates the work of typing out code doesn’t really change anything. Nobody who’s done any serious software development thinks that typing code is the important part of coding.
Anyone who makes lazy straw man arguments is betraying utter lack of intellectual integrity. Nowhere did I say their output is indistinguishable, what I actually said is that they work on the same principles. These are both stochastic systems.
The LLMs are very obviously mere tools that are instruments programmers use. Every tool can be wielded as a weapon, there’s nothing unique about LLMs in this regard. I also have no idea what this has to do with AI use disclosure which is the context for this thread.
How LLMs work is well understood, and that’s a completely different subject from how to use them effectively as a skill. With this in mind, the person who can’t even make a coherent argument, and keeps conflating unrelated things, is the actual charlatan here.
The LLM works on the exact same principle as autocomplete does. You’re just drawing an arbitrary line on technology you’re used to.

LLM is a tool that a human uses, do you also credit your IDE when you write code?
I assume you’re citing a couple of studies with tiny samples that have been going around here. There’s very little solid evidence to support the claim that LLMs demonstrably erode cognitive capacity. But if you have large scale, peer reviewed studies definitively showing this to be the case feel free to share them.
People lose certain skills working with LLMs, but that has always been the case with automation. Very few people know how to write assembly by hand, and practically nobody knows how to operate punch cards. Yet, we hardly claim that there was some loss of cognitive capacity as a result. People just spend their time focusing on different things now.
And I’ve already explained to you why the focus on the tooling is deeply misguided. You ignored my points entirely, which tells me that you’re not actually trying to have a discussion in good faith here yourself.
The question is why it matters in the first place. As long as the person submitting code takes ownership of the code, and there is a review of the code being done the same as before, nothing actually changes. Your whole line of argument is absurd because it’s premised on the idea that we can trust code produced by a human more than code produced by an LLM. And that’s obviously not true because humans make mistakes all the time. So, the focus on how the code was produced is fundamentally misguided. The focus in any successful project is on validation through things like code reviews, specifications, testing, and other well established practices. That’s what responsible teams have always done.
That’s why open models you can run locally are so important. Rental LLMs will absolutely get locked down sooner or later. In fact, that’s already happening with American ones where they’ll refuse to do certain tasks.

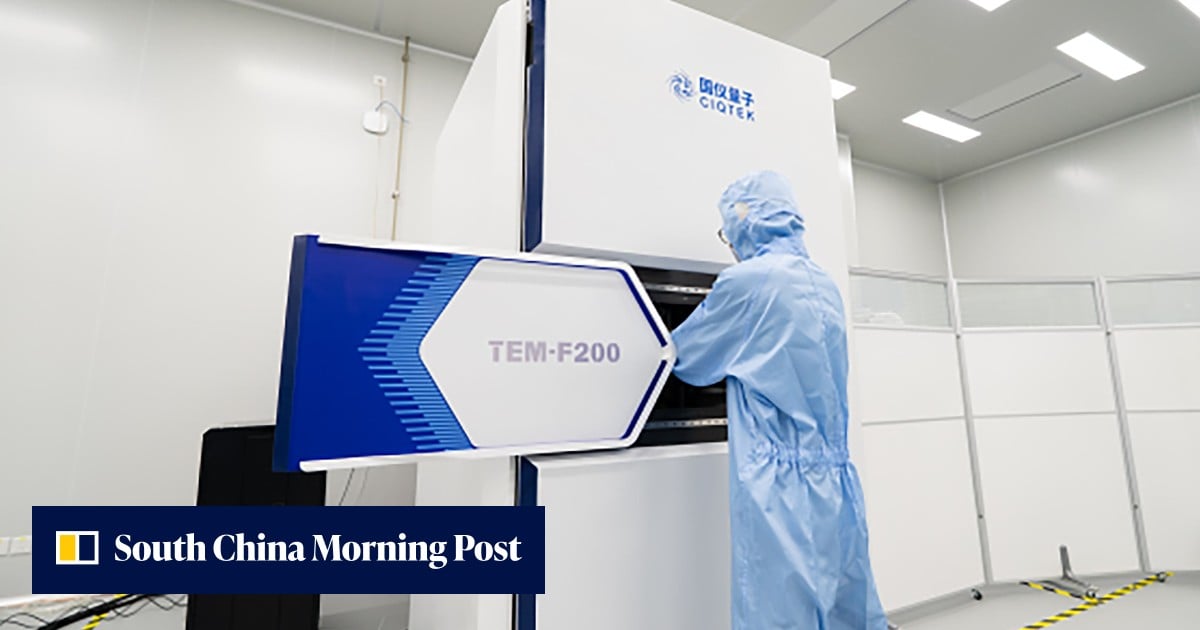
CXMT is entering mass production of 5th-generation DRAM which people thought wouldn’t be possible for years https://www.cxmt.com/en/news/info_22.html
You have absolutely no clue how LLMs work. It’s a neural network generalizes patterns that get imprinted onto it during training. And then these patterns are expressed in the given context during inference. People tend to confuse the output looking similar to training data with the mechanism being simple retrieval. While these agents do not think or feel, describing what they do as storing things in a database and pulling them up later is grossly incorrect. This framing fundamentally misrepresents how LLMs actually store and retrieve information.
There is no database or a lookup table, and there is no copy of any text they were trained on tucked away somewhere inside the weights. What they have is a compressed statistical model of the patterns that exist across trillions of tokens the text was broken down into. When you ask an LLM a question it does not go find the relevant passage and regurgitate it. What actually happens is that it generates text token by token based on the probability distribution it learned during training. It’s more akin to the way state machines like Markov chains work.
If anything, the way LLMs work is actually much closer to how humans improvise or combine ideas than to how a search engine or database works. When you write a sentence, you don’t pull up a specific sentence you memorized from a book and copy it. You’ve absorbed the patterns from countless examples of language over your lifetime and internalized them. Writing is a process of generating novel combinations based on those patterns.
Similarly, the weights of a model encode statistical regularities about word co occurrence, syntactic structures, semantic relationships, and higher level conceptual patterns. When it generates text it is combining those patterns in ways that were never present in the training data. That’s how LLMs produce entirely novel sentences that have never been written before, and why they can be prompted to combine ideas from different domains in creative ways.
LLMs do reproduce training data verbatim in some cases, but this happens because of overfitting on rare or repeated sequences. When a specific string appears many times in the training data like a famous quote or a common error message the model learns to assign an extremely high probability to each token in that exact sequence. So when it generates it follows the most likely path to reproduce the original text. It is similar to how a human can memorize a song or a poem by hearing it many times but that does not mean our general language ability works by pulling up stored copies from memory.
The notion that LLM assisted coding is equivalent to ordering from the menu at a restaurant is laughably naive. You seem to think that it’s like a slot machine where you put a query in and then you either get a correct result or some nonsense and you have to try again.
The way this process actually works is that you start by understanding the problem and figuring out how you want to solve it in terms of architecture, data structures, and algorithms that will be used. Then you get the LLM to come up with a rough shape of the solution, and iterate on it until it works the way you want. In practice, it’s like working with a genetic algorithm.
The core skill in using these tools is the same as the skill you need when writing code by hand. You have to understand the given requirement, the shape of the solution, and how to verify that the code that was produced actually matches the intent.
It’s ironic that you talk about AI only copying while uncritically regurgitating nonsense yourself.