

6·
5 days agoA majority of software runs on OSS. Your CIO is an idiot.
A majority of software runs on OSS. Your CIO is an idiot.
Holy fucking shit… rational conversations when talking about AI tool usage on Lemmy? WTF?!

It would be like KFC saying you can’t try to figure out how we made this food by eating it and taking the food apart and tasting it and testing it. And, again in my opinion, contract law (i.e., the terms of use for using the models) also does not provide the companies a viable claim because of a weird section of copyright law that basically doesn’t allow state law claims, such as contract claims, to be brought when they are in effect basically copyright claims.
This is what most people don’t understand. Looking at a picture or looking at a web page is not stealing. Also, you can’t compress the entirety of “the internet” into a 20-200GB model. The claim that the data they store are even close to exact representations is bunk.
Oh, you’re using this argument to claim that models shouldn’t be considered confidential and “trade secrets”. Well, yeah, but also that argument can be turned the other way. Fair use still stands.
And I know you’re an IP attorney and all, but I would be okay if LLMs end up destroying the entire framework of copyright. It is a system created by the rich, to be only abused by the rich. We’re already seeing it slowly get dismantled first-hand with all of these decompiling experiments, and I’m sure that will be followed up with rich megacorps doing what they do best: playing the hypocrite by claiming one thing is infringing in their copyright, while what they do is totally legal.
It doesn’t help that the OP is some power mod for 8 different communities and posts about 30 articles a day. Bot or real person? Hard to tell.
Originally published: Lawfare on October 8, 2026 by Lisa Klaassen
Then post the original goddamn link! Some stupid blog site regurgitating stories from real news sites.

Yeah, all of Graham Dot Zip’s interviews are fake. One of his videos had a separate tab, where it was obvious he was prompting an agent for the setup.
His entire channel is just this whole fake premise.

This thread is a worse dumpster fire than I thought. I figured people would just make the obvious Spiderman 2 joke.
If you’re building something new, why use coal? Just sidestep the obvious pollution and go straight to greener power sources. Hell, beef up the nuclear plants. That’s still way better than coal.
The entire point of the study was to see what kind of context files were useful and which were useless,
The title of the Pivot-to-AI article is: “Your AGENTS.md file doesn’t actually do anything”
These two statements don’t jive.
So when you say that they “admitted that they started with useless context files”, you are referring to the results of the study. Complaining that they didn’t base their study on the conclusions of that very study is just absurd
This is the difference between “we found a lot of useless AGENTS.md files” and “AGENTS.md files cannot possibly be useful at all”. The second is the argument the article is making. The first is the argument the research paper is making, which like most things on the Internet, is effectively a tautology. Most of the internet is useless, and most people are too criminally stupid to even operate a computer.
Bad research is still bad. The main paper is 9 pages with wide margins, outside of references. This was a few college students publishing their CS research assignment. The “Limitations” section is rather telling:
Another interesting avenue opened by this work is how to improve the automatic generation of useful context files.
Okay, so they already admitted that they started with useless context files, which sabotages their own test.
You know how you fix useless context files? You iterate until they are useful context files!
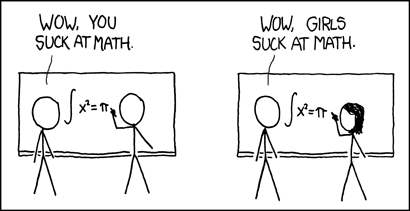
This whole research paper is XKCD 385, except with AGENTS.md files.
READMEs are for humans. AGENTS.md are for LLMs. LLMs are pretty good at reading READMEs, but READMEs tend to be overly verbose and too focused on using the code.
This is a load of shit. AGENTS.md is just a rules file for a repo like anything else. Properly-written rules files give good direction into how to interact with a project. If you don’t think it’s being read, ask the agent, and figure out why.
Far too many of these LLM articles are:
You don’t do the thing and pretend the first draft is going to work perfectly. You iterate, ask the agent directly why it didn’t work or what kind of improvements could be made, and improve the process.
Most of the time when I’m running through a repetitive process with a skill, I ask, “hey, what pitfalls did we learn from this process and how can we improve this skill?” Boom, iteration.
Also, Pivot-to-AI is just some guy’s anti-AI blog site. He does the same shit on YouTube.
If you were actually in the professional world where people are using and learning alongside these new tools, you wouldn’t be so dismissive about it.
That’s what I don’t get. Do these people not have a working job? Are they driving a truck or doing manual labor? Do they work as a store clerk? Are they all stuck in the creatives industry?
Like, if you’re sitting in front of a computer as part of your job, you’re using LLMs. And if you aren’t, you’re probably using them indirectly and don’t even know it.
we would have also missed the train of the blockchain and NFTs.
Only an idiot that hasn’t used the tech compares LLMs to blockchain or NFTs.
And how could this amazing technology that literally doesn’t have a single positive point,
Again, hasn’t used the tech, and you’re stuck in defiant rage mode.
Well, fuck… how could I possibly win such a well-versed argument like that?!
No, you!
I’m fine with AI. I’m not fine with slop. Ban slop, not LLMs.
Maybe we use AI to detect the bad AI, and then blame that AI when it doesn’t work?
This is one of those statistics where wasting time with more research is actively killing people. But, of course, we’ll continue to do so for the next decade while we really really know for sure that a passive test doesn’t somehow harm the population.
Meanwhile, wonder drugs that actually do kill people are just pushed on through while the evidence gets buried.



This is why the entire system of “just trust this random company, bro” certificate exchanges is broken at a foundational level.